How to Build an AI-Ready Data Pipeline: Quality, Freshness, Ownership, and Governance
October 12, 2026
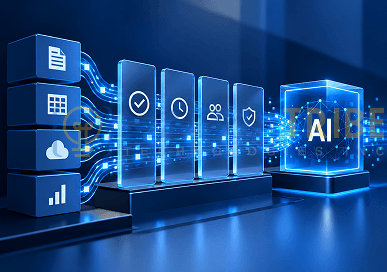
A data pipeline can run without errors and still deliver data that is stale, incomplete, inconsistent, or poorly controlled. For AI systems, those weaknesses affect output reliability.
An AI-ready data pipeline does more than move data. It keeps data accurate enough for its intended use, current enough for the decision, clearly owned, and governed throughout its lifecycle. AWS’s Generative AI Lens data architecture guidance similarly identifies data quality, security, privacy, lineage, and observability as important considerations for generative AI data architecture.
That requires quality, freshness, ownership, and governance to work together. If you are still deciding which initiatives deserve investment, MatrixTribe’s AI use case prioritization framework explains how data readiness should influence that decision.
When an external partner builds or manages the infrastructure, you also need to evaluate how access, changes, security, and operations are controlled.
What Makes a Data Pipeline AI-Ready?
A reliable pipeline moves data as expected. An AI-ready pipeline also keeps the resulting data suitable for the AI system consuming it.
You need to know whether the data is reliable enough and current enough for the intended use. You also need clear accountability for its condition and defined rules for how it is accessed, moved, and used. The pipeline should be designed to maintain those conditions continuously.
Build Measurable Data Quality Into the Pipeline
AI systems depend on the condition of the data they receive. Incomplete, duplicated, inconsistent, or incorrectly transformed records weaken that foundation even when the pipeline itself is technically healthy.
Define the Quality Rules That Matter
Start by defining acceptable data quality for the specific AI use case. Google Cloud’s data quality framework distinguishes dimensions including completeness, validity, consistency, accuracy, and uniqueness.
Those dimensions need measurable rules. Required fields should not be empty. Transaction values should stay within accepted ranges. Duplicate records should be identified before they reach downstream systems.
Automate Data Validation
Quality checks should run as part of the pipeline instead of depending on manual review. That includes required-field checks, duplicate detection, referential checks, transformation validation, range checks, and unexpected record-volume checks.
The goal is to turn quality into conditions the pipeline can test consistently. MatrixTribe’s Data Intelligence Pipeline services apply the same principle across data integration, validation, automation, and monitoring.
Define Data Freshness Around the AI Use Case
Data does not need to be real-time to be AI-ready. It needs to be current enough for the decision, prediction, or response the AI system produces.
Determine How Current the Data Needs to Be
Freshness depends on the use case. A monthly forecasting model can use scheduled batch updates. An internal knowledge assistant needs recent enough content to avoid outdated information. Fraud detection requires much tighter update windows.
Google Cloud defines freshness around when data was last updated and whether it remains recent enough to be useful. The requirement should come from the use case instead of an assumption that faster is always better.
Set Freshness Thresholds
For each critical dataset, define how often new data should arrive, how old it can become before it is stale, and how much processing delay is acceptable. A freshness SLA can formalize those expectations where the use case justifies it.
Decide What Happens When Data Becomes Stale
Define the state the system enters when a freshness threshold is missed. The dataset can be marked as stale, downstream use restricted, or the last trusted dataset used instead. Detection and escalation belong to production monitoring, which we cover later.
Assign Ownership Before AI Depends on the Data
Data issues become harder to resolve when responsibility is unclear. Before an AI system depends on a dataset, you should know who is accountable for its meaning, quality expectations, and technical operation.
Microsoft Purview separates responsibilities across data owners, data stewards, and governance roles. These responsibilities include quality, classification, access, consistency, and lineage.
Separate Business Ownership From Technical Ownership
Business ownership covers what the data represents, how it should be interpreted, what quality level is acceptable, and whether it remains appropriate for the intended AI use.
Technical ownership covers ingestion, transformation, delivery, and maintenance. Keeping those responsibilities distinct prevents a gap where engineering keeps the pipeline running while nobody owns whether the data still supports the business use case.
Define Escalation Responsibilities
Assign accountability before conditions change. Decide who owns a source change, quality failure, availability issue, or change in the AI use case.
This connects data ownership to the wider organizational readiness required for AI, where ownership and governance become part of moving systems from pilots into production.
Embed Governance Into the Data Flow
Governance defines the rules under which data can be accessed, moved, retained, and used. For AI pipelines, those controls should operate through the data flow rather than exist only in policy documents.
Classify Data Before AI Uses It
Identify what type of data moves through the pipeline. Personal information, confidential business data, restricted records, and public data require different levels of protection. Classification determines which controls apply before data reaches an AI system.
Control Who and What Can Access the Data
Access should be limited to the users, services, and AI systems that require it. Apply least-privilege principles, define approved uses, and review access when systems or responsibilities change. Microsoft Purview also places classification, access, and quality responsibilities within its governance model.
Maintain Metadata and Data Lineage
You should be able to trace where important data came from, how it was transformed, and which downstream systems depend on it. Metadata and lineage make that path visible. They also help you investigate quality problems and assess the effect of source or transformation changes.
Define Retention and Usage Rules
Set rules for how long datasets are retained, when they should be removed, and whether contractual, regulatory, or internal requirements restrict their use by an AI system. Retention should reflect the purpose of the data instead of defaulting to indefinite storage.
Use Verifiable Controls to Strengthen Data Governance
When an external partner builds or manages your pipeline, you also rely on how that partner handles access, system changes, security operations, and software delivery.
MatrixTribe’s SOC 2 Type II compliance provides added assurance around the security and operational controls supporting our delivery. SOC 2 Type II does not guarantee data quality or AI accuracy. It provides stronger evidence that the surrounding control environment operates consistently over time. That matters when you select a partner to build infrastructure production AI systems will depend on.
Monitor Data Health in Production
Once the pipeline is live, you need visibility into technical failures and changes in the data itself. AWS recommends data observability across areas including data quality, pipeline performance, lineage, anomaly detection, and performance metrics.
Monitor Pipeline Health and Data Health Separately
Pipeline health covers failed jobs, processing delays, connection failures, and infrastructure problems.
Data health covers quality-rule failures, freshness breaches, missing records, and unexpected changes in volume.
Monitoring both shows whether the pipeline is running and whether its data remains usable.
Detect Changes Before They Reach AI Systems
Source systems change over time. Fields are added or removed, data types change, and schemas drift. Detect those changes before they alter downstream AI inputs. Structural monitoring shows where validation, transformation, or integration logic needs updating.
Define Alerts and Response Paths
Set thresholds for critical failures and define which technical condition triggers an alert or blocks downstream use. Route the issue to the owner already assigned to that dataset or pipeline.
The response should match the severity of the issue and the risk of unreliable data reaching the AI system.
How to Build an AI-Ready Data Pipeline Step by Step
Once the requirements are clear, the build should connect the AI use case to the controls supporting it.
Phase 1: Define the Data Requirements
Start with the AI use case and identify the datasets it depends on. Define quality expectations, freshness thresholds, ownership, and usage restrictions before building the pipeline.
Phase 2: Build the Controls Into the Pipeline
Create the ingestion and transformation workflows. Add automated validation, classification, access controls, metadata, and lineage as part of the pipeline.
Phase 3: Operate and Improve the Pipeline
Monitor pipeline performance and data health. Establish alerts and response paths, then review requirements as sources, datasets, and AI applications change. This keeps the pipeline aligned with the conditions the AI system depends on over time.
Conclusion
An AI-ready pipeline keeps data suitable for the use case, current enough for the decision, owned by accountable people, and governed through clear controls. Quality tells you whether the data is reliable. Freshness tells you whether it is current enough. Ownership establishes accountability. Governance defines how it is accessed and used. Monitoring tells you when those conditions change.
At MatrixTribe, our Custom AI Development services connect production AI systems to the data, integrations, and architecture they depend on. We build those systems around measurable quality controls, governed access, traceability, and monitoring. Our SOC 2 Type II compliance adds assurance that the surrounding security and operational controls are managed through an established control environment.
Contact MatrixTribe if you need a data engineering partner that combines AI-ready pipeline design with disciplined security and operational controls.
Published
Latest Article
 October 12, 2026
How to Build an AI-Ready Data Pipeline: Quality, Freshness, Ownership, and Governance
Read Article October 5, 2026
Cybersecurity Compliance in Canada: SOC 2 Type II and PIPEDA
Read Article